⚡ R.I.P. NotebookLM
- Alex Prompter from ⚡ AI Superpowers <aisuperpowers@substack.com>
- Hidden Recipient <hidden@emailshot.io>

Read time: 5 minutes | Unlock my Claude Skills Bundle Hey friend, Alex here. Google just had the worst month of its AI life. The flagship model slipped its launch window, the stock dropped about 4%, and half my timeline spent the week writing its obituary. Then Google renamed the one tool of theirs I’d fight to keep. NotebookLM is now Gemini Notebook. The site and your notebooks are untouched; the rename is mostly a new logo. What matters is the thing it was already doing: it reads only the documents you give it, which means it can tell you which of your sources disagree with each other, and which one said what. Today:
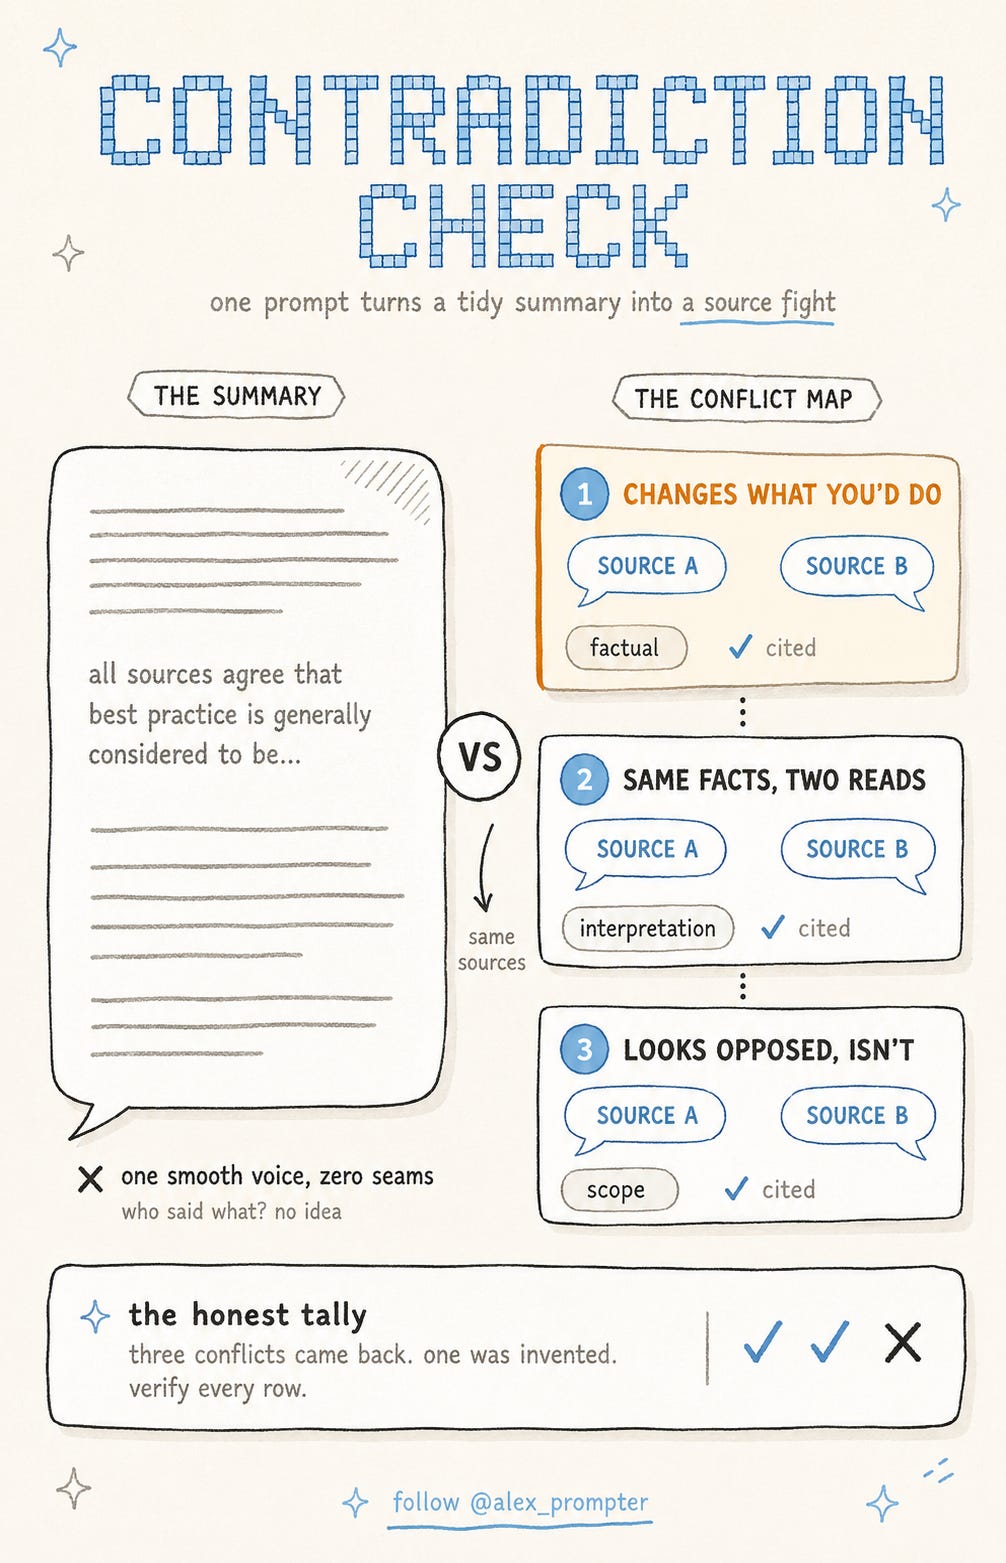
WHAT EVEN IS RAG?No, not the thing you use to wipe down the kitchen counter. RAG stands for retrieval-augmented generation, and it means the model answers from documents you hand it rather than from memory. Think of it as a closed-book exam versus an open-book one. A chat model sits the exam from memory, and when a detail has gone fuzzy, it fills the gap with something that sounds right. You can’t tell the recalled parts from the invented ones, because both arrive in the same confident voice. Open-book changes two things. You choose which books go on the desk, so you control what counts as evidence. And the answer has to point at a page, so you can check it. That’s the trade: you give up the model’s general knowledge and get back an answer you can audit. ⚡ THE SUPERPOWER: The Contradiction CheckPeople upload six documents, ask for a summary, and get back a tidy consensus that reads well and feels like understanding. But a summary is built to smooth things over. When your sources disagree, it picks one, splits the difference, or drops the argument and reports what everyone agreed on. The disagreement was why you gathered six sources instead of one, and the summary is where it goes to die. The consensus is the part you’d have gotten from any single source. The disagreements are where the real understanding lives, and they’re the only part a chat model can’t show you, because it has no idea which of its memories came from where.
So I picked three documents that should agree and mostly don’t: the current official prompting guides from Anthropic, Google, and OpenAI. Three companies explaining how to talk to their own models. ⚙️ THE WORKFLOWGetting the sources in is the part nobody writes about, so I’ll go first. Pasting the URLs failed. All three are JavaScript-heavy doc sites, and two of them imported as navigation menus, a list of links where the guide should have been. Nothing errors, which is the dangerous bit: the notebook carries on answering from whatever it grabbed. The fix took a while to find. Most doc sites publish a clean text copy of themselves for this reason. Anthropic’s has a “Copy page” button, and adding Then verify, before you ask anything else: If a source answers with link text or a short section count, rebuild it. A notebook holding one real document and two hollow ones doesn’t warn you; it writes the same confident answer either way. Once all three check out, paste this: Ask a general question, and you get forty rows of “only this source mentions X,” which is coverage difference wearing a conflict costume. Splitting the answer into four parts fixes that. Part 1 holds the head-to-head fights, and capping Part 2 stops them flooding it. The results came back messier than a clean win, and more useful. It returned 3 direct conflicts. The first was real: Google recommends always including few-shot examples, meaning worked examples of the task inside your prompt, while OpenAI reports better scores from stripping prompts down. I’d never have caught that reading all three back to back. It invented the second one. It claimed Anthropic and Google disagree about where instructions go in a long prompt. They don’t. Anthropic says put the documents at the top with your question below them; Google says context first and instructions at the very end. That’s the same instruction described from two angles, and it ranked second out of three. It also miscredited XML tags as Anthropic-only, when Google’s guide recommends them by name and includes a template. And it pinned a 10 to 15% improvement figure on dropping examples, when the source credits that gain to leaner prompts overall. It missed at least three real conflicts in those same files, including one lab contradicting itself on a single page. Of three headline findings, one was fake, and one carried a broken number. Six free queries and 10 minutes for two solid leads, plus a fake I had to catch. The honest verdict is that this generates leads you then go and check. Treat every row as a claim, including the order they arrive in, because the invented conflict placed above a real one. It also reads length as significance: feed it three files of different sizes and it’ll tell you the small one had less to say. Want the version that catches more? Run it twice with the source order reversed. Anything surviving both passes is probably solid; anything appearing once is where I’d start. 💬 PROMPT OF THE DAYWhy it works: it forces the model to name its own failure conditions and attach a date to them, so the advice arrives with an expiry instead of sounding permanently true. Best on: any model. 📚 USEFUL RESOURCES
What should I break down next: a Claude skill that reviews your work before you ship it, or an automation that runs while you sleep? Hit reply, one word is enough. Know someone who learns everything from a single chat window? Forward them this. And as always, remember: LLMs don’t think, you do. ⚡ Alex Prompter P.S. Today’s Contradiction Check is one prompt. My Claude Skills Bundle turns Claude into 20+ specialists for marketing and business. Grab yours here: linktr.ee/alex_prompter You're currently a free subscriber to ⚡ AI Superpowers. For the full experience, upgrade your subscription.
|




Similar newsletters
There are other similar shared emails that you might be interested in: